A systems engineer is updating firmware across a large DGX cluster using automation.
What is the best practice for minimizing risk and ensuring cluster health during and after the process?
- A. To save time, simultaneously update all nodes in the cluster without draining or diagnostics. B. Drain nodes from the scheduler, run pre-update diagnostics, update firmware in batches, and verify health post-update before scaling to the next batch.
- C. Drain nodes from the scheduler, update firmware in batches, skip diagnostics and verify health post-update before scaling to the next batch.
- D. Update nodes that have reported faults, leaving others on older firmware.
시스템 엔지니어가 자동화 도구를 사용하여 대규모 DGX 클러스터의 펌웨어를 업데이트하고 있습니다.
이 과정 중 및 완료 후 위험을 최소화하고 클러스터의 상태를 보장하기 위한 최적의 방법은 무엇일까요?
- A. 시간을 절약하기 위해 노드 드레인이나 진단 없이 클러스터의 모든 노드를 동시에 업데이트합니다.
- B. 스케줄러에서 노드를 드레인하고, 업데이트 전 진단을 실행하고, 펌웨어를 일괄적으로 업데이트한 후, 다음 일괄 업데이트를 진행하기 전에 업데이트 후 상태를 확인합니다.
- C. 스케줄러에서 노드를 제거하고, 펌웨어를 일괄 업데이트하고, 진단을 건너뛰고, 다음 일괄 업데이트로 확장하기 전에 업데이트 후 상태를 확인합니다.
- D. 오류가 보고된 노드는 펌웨어를 업데이트하고, 나머지 노드는 이전 펌웨어를 유지합니다.
정답은 B입니다. ✅
Drain nodes from the scheduler → Run pre-update diagnostics → Update firmware in batches → Verify health after update → Proceed to next batch
이 방식이 가장 안전한 rolling/batched upgrade 접근입니다.
NVIDIA 공식 DGX 펌웨어 가이드는 업데이트 전에 불필요한 시스템 활동과 GPU workload를 중지하고, 업데이트 중 추가 부하를 주지 말라고 안내합니다. 또한 여러 DGX 시스템을 nvfwupd로 업데이트할 수 있으며, 다중 시스템 업데이트는 순차적으로 수행할 수 있습니다. NVIDIA Docs
초보자식으로 보면
예를 들어 DGX 노드가 100대 있다고 하면:
Node 1~10
  ↓
Scheduler에서 Drain
  ↓
사전 진단
  ↓
Firmware Update
  ↓
재부팅/필요한 Reset
  ↓
GPU / Network / Health 확인
  ↓
정상 확인
  ↓
Node 11~20 진행
이렇게 조금씩 나눠서 업데이트하는 것이 핵심입니다.
Drain이 뭐죠?
Slurm 같은 Scheduler에서 해당 노드에 새로운 Job이 들어가지 못하게 막는 것입니다.
정상 상태
User Job → DGX Node

Drain 상태
User Job ─X→ DGX Node
현재 실행 중인 작업도 적절하게 종료시킨 뒤 펌웨어 작업을 진행합니다.
즉:
“이 서버는 지금 유지보수 중이니 작업 보내지 마세요.”
라는 뜻입니다.
왜 사전 진단이 중요한가?
업데이트 전에 이미 고장난 GPU가 있었다고 해보겠습니다.
업데이트 전
GPU 3 ECC 오류 존재
       ↓
Firmware Update
       ↓
업데이트 후에도 GPU 3 오류
사전 진단을 안 했다면:
"펌웨어 업데이트 때문에 GPU가 고장났나?"
라고 오해할 수 있습니다.
그래서:
Pre-check
    ↓
기존 상태 기록

Firmware Update

Post-check
    ↓
업데이트 후 상태 비교
가 중요합니다.
NVIDIA도 GPU 시스템의 운영 상태를 판단하기 위해 DCGM 등으로 GPU metrics와 health 정보를 수집하는 것을 권장합니다. NVIDIA Docs
왜 한 번에 전부 업데이트하지 않나요?
A처럼:
모든 노드를 동시에 업데이트
하면 아주 위험합니다.
예를 들어 Firmware 자체에 문제가 있으면:
100대 동시 Update
       ↓
Firmware 문제 발생
       ↓
100대 모두 영향
       ↓
Cluster 전체 장애 💥
반대로 10대씩 하면:
1차 10대
 ↓
문제 발견
 ↓
중단
 ↓
나머지 90대 보호
가 가능합니다.
이게 Blast Radius를 줄이는 방식입니다.
보기별로 보면
A ❌
모든 노드를 동시에 업데이트하고 Drain과 진단도 안 합니다.
가장 위험한 방식입니다.
B ✅
Drain
→ Pre-diagnostics
→ Batch update
→ Post-health check
→ Next batch
모든 안전 절차가 포함되어 있습니다.
C ❌
거의 맞지만:
skip diagnostics
가 문제입니다.
사전 상태를 모르면 업데이트 전후 비교가 어렵습니다.
D ❌
장애가 난 노드만 업데이트하면 클러스터 내 Firmware 버전이 섞일 수 있습니다.
Node1 → FW v1
Node2 → FW v2
Node3 → FW v1
Node4 → FW v2
이런 version skew는 운영과 장애 분석을 복잡하게 만들 수 있습니다.
🎯 시험 암기법
이 순서를 그대로 기억하세요.
Drain → Diagnose → Batch → Verify → Next
조금 더 풀면:
Drain
  ↓
Pre-check
  ↓
Firmware Update
  ↓
Post-check
  ↓
정상 확인
  ↓
Next Batch
한 줄 암기
대규모 DGX Firmware Update = Drain + Pre-check + Batch + Post-check
정답: B ✅
이 문제에서는 특히 B와 C의 차이가 pre-update diagnostics 유무라는 점을 잡으면 바로 풀립니다.
========================
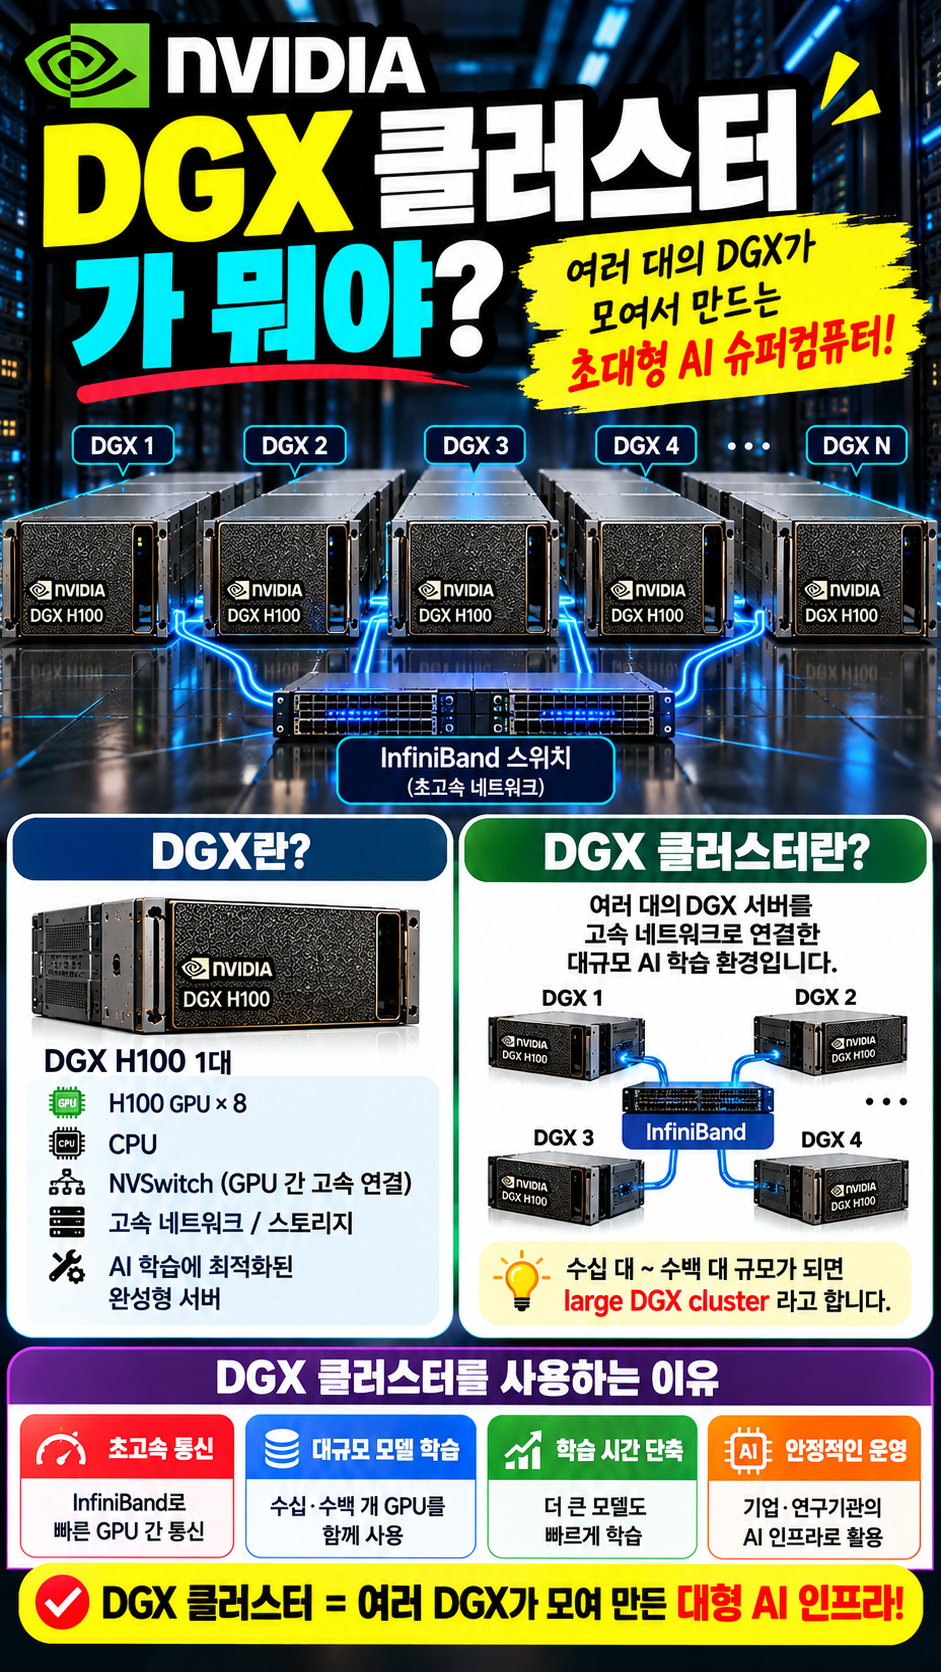
a large DGX cluster
DGX 서버 여러 대를 아주 많이 묶어서 하나의 대형 AI 슈퍼컴퓨터처럼 사용하는 환경
입니다.
먼저 DGX가 뭐였죠?
앞에서 본 DGX H100은 NVIDIA의 완성형 AI 서버입니다.
예를 들어 DGX H100 1대에는:
H100 GPU × 8
CPU
NVSwitch
고속 네트워크
스토리지
가 들어 있습니다.
즉:
DGX 1대 = 강력한 GPU 서버 1대
입니다.
그럼 DGX Cluster는?
DGX 서버 여러 대를 네트워크로 연결하면:
DGX 1
DGX 2
DGX 3
DGX 4
...
이게 DGX Cluster입니다.
구조로 보면:
DGX Node 1 ─┐
DGX Node 2 ─┤
DGX Node 3 ─┼── InfiniBand / Ethernet Switch
DGX Node 4 ─┤
DGX Node 5 ─┘
이 전체를 하나의 거대한 AI 학습 환경으로 사용합니다.
large는 어느 정도라는 뜻?
정확히 몇 대부터 large라고 정해진 건 아닙니다.
문맥상:
DGX 몇 대가 아니라
DGX 수십 대
DGX 수백 대
처럼 운영 자동화가 필요할 정도의 큰 환경을 뜻합니다.
예를 들어 DGX H100이 100대라면:
100 nodes × 8 H100 GPUs
= 800 H100 GPUs
가 됩니다.
이 정도면 대규모 AI 학습용 클러스터입니다.
왜 Cluster로 묶나요?
AI 모델이 너무 커서 GPU 8개만으로 부족할 수 있기 때문입니다.
예를 들어:
DGX 1
H100 × 8
만으로 학습하기 어려운 모델이라면:
DGX 1 → H100 × 8
DGX 2 → H100 × 8
DGX 3 → H100 × 8
DGX 4 → H100 × 8
총:
32 GPUs를 같이 사용할 수 있습니다.
여기서 NCCL과 InfiniBand가 중요해집니다.
GPU
 ↓
NCCL
 ↓
InfiniBand
 ↓
다른 DGX의 GPU
즉 여러 DGX 서버의 GPU들이 서로 통신하면서 하나의 큰 학습 작업을 수행합니다.
앞 문제와 연결하면
문장에서:
a large DGX cluster
는
DGX 서버가 많이 연결된 대규모 AI 인프라
라는 뜻입니다.
그래서 펌웨어 업데이트도 한 번에 다 하면 위험합니다.
DGX 100대 전체 동시 업데이트
→ 문제 생기면 전체 영향
그래서:
10대 Drain
→ Update
→ Health Check
→ 정상 확인
→ 다음 10대
처럼 나눠서 처리하는 겁니다.
시험용 한 줄 암기
DGX = NVIDIA AI 서버
DGX Cluster = 여러 DGX 서버를 고속 네트워크로 연결한 AI 클러스터
Large DGX Cluster = 수십~수백 대 규모의 대형 DGX 환경
앞으로 문제에서 node, cluster, fabric, DGX가 같이 나오면 이렇게 연결하면 됩니다:
Node = 서버 1대
Cluster = 서버 여러 대
Fabric = 서버들을 연결하는 네트워크 전체
DGX Cluster = DGX 서버 여러 대를 연결한 AI 환경

댓글